PolyStep.jl




PolyStep.jl minimizes black-box functions that have no useful gradient. Examples are losses that are piecewise constant, losses that go through an argmax or a combinatorial solver, and outputs of integer-valued simulations. It is the Julia version of PolyStep (TMLR 2026).
Each step puts a randomly rotated polytope around the current point. It evaluates all vertices in one batched call and moves to a softmax-weighted average of the vertices. The vertices are at a finite distance, so a step can cross flat regions where the gradient is zero. The same seed gives bit-identical results on any number of threads.
Paper · Interactive visualization · Guide · Benchmarks
| One particle | Four particles, two minima |
|---|---|
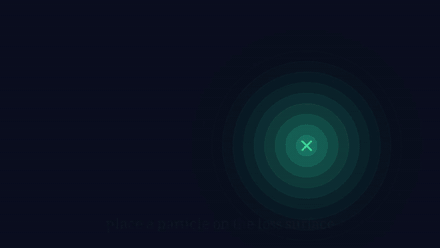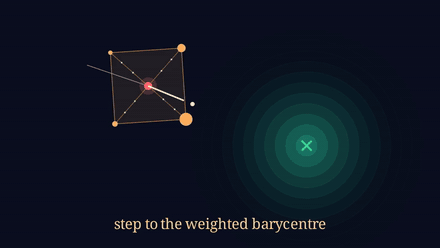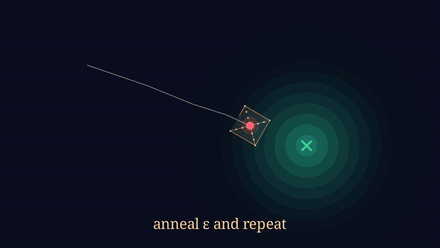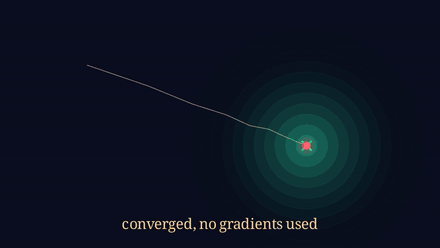 | 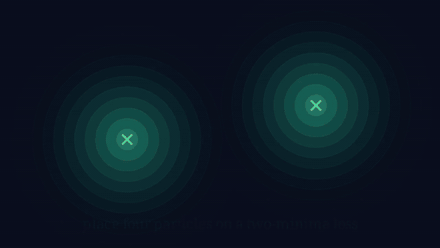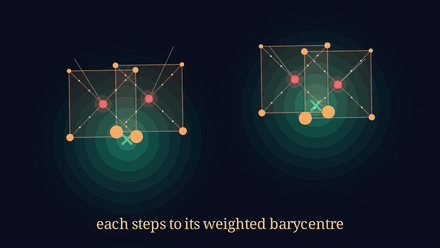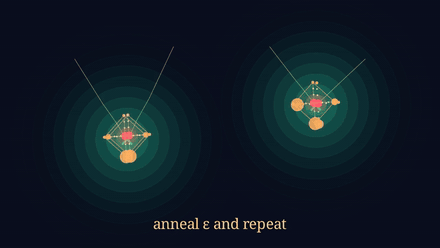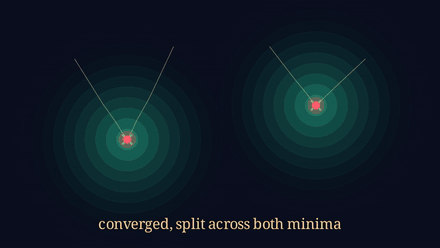 |
The animations come from the interactive visualization by Viet T. Nguyen.
Installation
using Pkg
Pkg.add("PolyStep")
Quick start
using PolyStep, Random

# batched objective: (d, N) candidate columns -> N costs.
# Piecewise constant, zero gradient almost everywhere, minimum 0.
f(X) = vec(sum(floor.(abs.(X)); dims = 1))

x0 = fill(5.5, 10)
es = minimize(f, 10; steps = 100, epsilon = 0.1, step_radius = 1.0, x0,
              rng = Xoshiro(0))
println((f0 = f(reshape(x0, :, 1))[1], best_f = es.best_f, evals = es.evals))
# (f0 = 50.0, best_f = 0.0, evals = 2001)
The radius must be larger than the flat regions. With step_radius = 0.5, all vertices cost 50, the weights are uniform, and the iterate stays at x0.
Ask/tell, with bounds and integrality repair:
cost(X) = vec(sum(abs2, X .- 3.4; dims = 1))   # best integer point: fill(3.0, 5)

es = PolyStepES(5; epsilon = 0.1, step_radius = 1.0, x0 = fill(9.0, 5),
                lb = 0.0, ub = 10.0, repair = X -> round.(X))
for _ in 1:100
    X = ask!(es)          # (dim, popsize) columns, clamped and repaired
    tell!(es, cost(X))
end
println((best_x = es.best_x, best_f = es.best_f))
# (best_x = [3.0, 3.0, 3.0, 3.0, 3.0], best_f = 0.7999999999999996)
minimize and PolyStepES accept entropic optimal transport and greedy solvers, box bounds, a repair function and a geometric radius_decay. minimize also takes a callback. PolyStepConfig with step! and solve! adds simplex and cube templates, epsilon schedules, momentum, an adaptive radius and biased rotations. It also has a quadratic model with Newton refinement and a trust region. HybridSubspace searches a subspace of the parameters of a model, layer by layer. PolyStepOptimizer connects the package to Optimization.jl. With LoopVectorization loaded, the Sinkhorn and KL kernels run faster, and PolyStep.cuda_objective evaluates an objective on a GPU. The guide explains tuning, bounds, solvers, threads and subspaces. The package needs Julia 1.10 or later.
When to use it
Use PolyStep when the loss goes through argmax routing, a combinatorial solver or an integer-valued simulation, and a batch of evaluations is cheap.
Use a different method in these cases:
- One evaluation takes minutes: use Bayesian optimization.
- The problem is smooth and small: CMA-ES is usually better, and Nelder-Mead solves example 02 in 106 evaluations.
- A usable gradient or surrogate exists: in example 04, a Fenchel-Young loss needs approximately 200 times fewer solver calls.
- You need convergence guarantees with integer variables: use NOMAD.
Examples
Each script prints a results table and asserts its claim. All methods get the same evaluation budget and a tuning grid of the same size. The tuning uses training data only, and the grids are in the script headers. "CMA-ES" is IPOP-CMA-ES with restarts (ipop_cma.jl).
julia --project=examples -e 'using Pkg; Pkg.instantiate()'
julia --project=examples examples/01_hard_decision_tree.jl| # | Problem | Result |
|---|---|---|
| 01 | Hard oblique decision tree, 0-1 loss, 20 checkerboards, 40k evals | Median train/test accuracy: PolyStep 94.2/90.9%, IPOP-CMA-ES 87.7/83.3%, OpenAI-ES 85.4/80.8%, SPSA 84.6/80.4%. PolyStep has the higher test accuracy on 16-19 of 20 instances. |
| 02 | (s,S) inventory policy, 2-D, Poisson demand, 5 seeds | PolyStep, IPOP-CMA-ES and Nelder-Mead all reach the grid optimum. SPSA is worse at a 500-eval budget. |
| 03 | Contextual districting through a capacitated-MST decoder, 8000 decoder calls, 5 seeds | PolyStep 9.549, perturbed gradient + Adam 9.554, IPOP-CMA-ES 9.584. All are better than the true-cost decode (9.674) and within 0.4% of each other. |
| 04 | Decision-focused subset selection (DecisionFocusedLearningBenchmarks), 625 weights, hard top-k, 3 seeds | Test regret: PolyStep 2.27, Fenchel-Young 3.51, IPOP-CMA-ES 4.02 (untrained 6.51). PolyStep is lowest on every seed but uses approximately 200 times more solver calls than Fenchel-Young. |
| 05 | DFL with predicted knapsack weights, 10 seeds, 12k evals | PolyStep has the lowest median train regret (0.229 vs CMA-ES 0.302). On test it is 4.74, CMA-ES 4.67 and SFGE 4.90; the differences are within seed noise. |
We also ran the COCO bbob-mixint suite, where 80% of the variables are integers. In dimensions 5 and 10, PolyStep solves as many targets as the better CMA-ES, or more, up to 1000 * dim evaluations. With the full 10^4 * dim budget, it ties CMA-ES with margin, and pycma is better in dimension 10. The benchmarks page gives the details.
Maintainers
Citation
@article{le2026training,
  title   = {Training Non-Differentiable Networks via Optimal Transport},
  author  = {Le, An T.},
  journal = {Transactions on Machine Learning Research},
  year    = {2026},
  url     = {https://arxiv.org/abs/2605.01928}
}
See also CITATION.cff and the changelog.